Almost every app is a story about lists and lookups: a feed of posts, a table of settings, a cache keyed by ID. In Swift those stories are told with two collection types you’ll use every single day, Array and Dictionary. They look simple, but they hide a lot of clever engineering: copy-on-write storage, amortized growth, randomized hashing, and value semantics that make them safe to pass around.
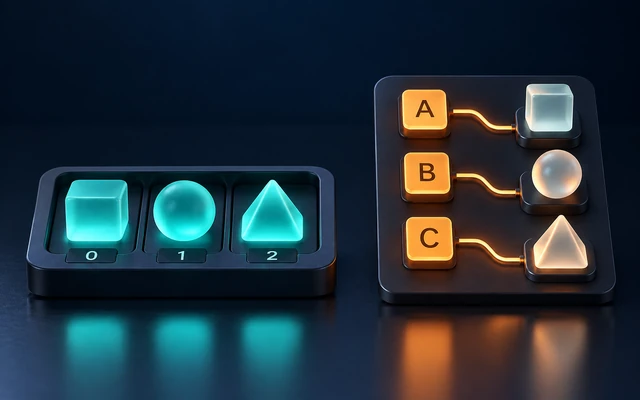
Arrays organize values by position; dictionaries associate keys with values.
This article goes beyond the syntax. We’ll look at how both types behave, how they’re implemented, what they cost, and the mistakes that cause real bugs in production apps.
Part 1: Arrays
Creating arrays
An array stores values of a single type in a specific order. Swift infers the type from a literal, or you can spell it out:
var languages = ["Swift", "Kotlin", "Rust"]   // [String]
var scores: [Int] = []                       // an empty array needs a type
let zeros = Array(repeating: 0, count: 3)    // [0, 0, 0]
let oneToFive = Array(1...5)                 // [1, 2, 3, 4, 5]
let characters = Array("hey")                // ["h", "e", "y"]
[Int] is shorthand for Array<Int>. Array is a generic struct, and the type parameter is fixed for the array’s whole life: scores can never hold a String.
Reading elements safely
Subscripting an index that doesn’t exist crashes with “Index out of range”. That’s deliberate: Swift would rather stop your app than let it read memory that doesn’t belong to the array. When an index might not be valid, check first, or use APIs that return optionals:
let first = languages.first          // String?
let last = languages.last            // String?
let random = languages.randomElement()  // String?

if languages.indices.contains(10) {
    print(languages[10])
}

if let index = languages.firstIndex(of: "Rust") {
    print("Rust is at index \(index)")
}
first, last, min(), max(), and randomElement() all return optionals, because the array might be empty. That’s the type system reminding you to handle the empty case.
Adding and removing
languages.append("Go")
languages.insert("C", at: 0)
languages += ["Zig", "Odin"]
languages[1] = "Swift 5"

let removed = languages.remove(at: 0)    // "C"
languages.removeAll { $0.hasPrefix("Z") } // removes "Zig"
print(languages)   // ["Swift 5", "Kotlin", "Rust", "Go", "Odin"]
Pay attention to the difference between these two:
var stack = [1, 2, 3]
let top = stack.popLast()       // Int? — returns nil on an empty array
let next = stack.removeLast()   // Int  — crashes on an empty array
Use popLast() when emptiness is a normal situation, and removeLast() when an empty array would be a bug.
Iterating
for language in languages {
    print(language)
}

for (offset, language) in languages.enumerated() {
    print("\(offset + 1). \(language)")
}

for index in languages.indices {
    print(index, languages[index])
}

let ranks = [1, 2, 3]
for (rank, language) in zip(ranks, languages) {
    print("#\(rank): \(language)")   // stops at the shorter of the two
}
enumerated() gives you an offset, a counter starting at zero, not an index. For a plain array they happen to be the same, but for slices they aren’t, as we’ll see below. If you need indices, iterate indices.
forEach looks similar to for-in, but you can’t break out of it, and return inside it only skips to the next element. Prefer for-in when you need control flow.
Transforming
Arrays shine with higher-order functions, which return new arrays instead of mutating in place:
let words = ["apple", "fig", "banana", "kiwi"]

let lengths = words.map { $0.count }                 // [5, 3, 6, 4]
let short = words.filter { $0.count <= 4 }           // ["fig", "kiwi"]
let totalLength = words.reduce(0) { $0 + $1.count }  // 18
let numbers = ["1", "two", "3"].compactMap { Int($0) } // [1, 3]
let flattened = [[1, 2], [3]].flatMap { $0 }         // [1, 2, 3]
let sortedWords = words.sorted()                     // alphabetical
let byLength = words.sorted { $0.count < $1.count }
reduce(into:) is the efficient way to build a collection, because it mutates one accumulator instead of creating a new one at every step:
let letterCounts = "mississippi".reduce(into: [:]) { counts, letter in
    counts[letter, default: 0] += 1
}
// ["i": 4, "s": 4, "p": 2, "m": 1] (in some order)
Chains like filter then map create an intermediate array at each step. For large inputs where you only need part of the result, lazy processes elements on demand:
let firstBigSquare = (1...1_000_000).lazy
    .map { $0 * $0 }
    .first { $0 > 10_000 }      // computes only 101 squares, not a million
Slices share storage
Subscripting with a range gives you an ArraySlice, a view into the original array’s storage. It’s created in constant time, without copying anything:
let allScores = [10, 20, 30, 40, 50]
let tail = allScores[2...]          // ArraySlice<Int>: [30, 40, 50]

print(tail.startIndex)              // 2, not 0!
print(tail[2])                      // 30
// print(tail[0])                   // crash: index 0 isn't part of this slice
Slices keep the indices of the original array. That’s the most common slice bug: code that assumes indices start at zero. Use startIndex, first, or iterate the slice directly.
A slice also keeps the whole original buffer alive. If you take a small slice of a huge array and store it for a long time, the huge array stays in memory. Convert it with Array(slice) when you keep it around.
Under the hood: how Array works
A tiny struct pointing at a buffer
An Array value is just a single reference to a heap-allocated buffer, which stores the count, the capacity, and the elements contiguously:
print(MemoryLayout<[Int]>.size)            // 8 bytes on a 64-bit device
print(MemoryLayout<[String: Int]>.size)    // 8 bytes too
However many elements an array holds, the array value itself is one pointer. That’s why passing arrays around is cheap.
Capacity and amortized growth
The buffer usually has room for more elements than it currently holds. That room is the capacity. When you append beyond it, Swift allocates a bigger buffer, roughly double the size, and moves the elements over. Measuring an array that grows one element at a time:
var growing: [Int] = []
var capacities: [Int] = []
for value in 0..<100 {
    growing.append(value)
    if capacities.last != growing.capacity {
        capacities.append(growing.capacity)
    }
}
print(capacities)   // [2, 4, 8, 16, 36, 76, 156] on a 64-bit Mac
The exact numbers depend on the memory allocator, but the pattern is geometric. Because each reallocation doubles the space, the expensive copies happen rarely, and appending is amortized O(1): averaged over many appends, each one costs a constant amount.
When you know roughly how many elements you’ll add, reserve the space once and skip the intermediate reallocations:
var ids: [Int] = []
ids.reserveCapacity(10_000)
for id in 0..<10_000 {
    ids.append(id)
}
Similarly, removeAll(keepingCapacity: true) empties an array but keeps its buffer, which is useful for an array you refill over and over, like a per-frame list in a game loop.
Copy-on-write
Arrays are value types: assigning one to another variable gives you an independent array. But copying the elements every time would be slow, so Swift uses copy-on-write (CoW). Copies share one buffer until one of them is modified, and only then is the data duplicated:
var original = [1, 2, 3]
var copy = original

original.withUnsafeBufferPointer { a in
    copy.withUnsafeBufferPointer { b in
        print(a.baseAddress == b.baseAddress)   // true: one shared buffer
    }
}

copy.append(4)

original.withUnsafeBufferPointer { a in
    copy.withUnsafeBufferPointer { b in
        print(a.baseAddress == b.baseAddress)   // false: copied on write
    }
}
print(original, copy)   // [1, 2, 3] [1, 2, 3, 4]
Before every mutation, the array asks: “am I the only owner of my buffer?” If yes, it mutates in place. If no, it copies first. You can build the same behavior into your own types with isKnownUniquelyReferenced(_:):
final class Storage {
    var values: [Int]
    init(values: [Int]) { self.values = values }
}

struct CoWList {
    private var storage = Storage(values: [])

    var values: [Int] { storage.values }

    mutating func append(_ value: Int) {
        if !isKnownUniquelyReferenced(&storage) {
            storage = Storage(values: storage.values)   // copy only when shared
        }
        storage.values.append(value)
    }
}
One practical consequence: CoW can make a seemingly cheap line expensive. If you hold a second reference to an array, for example a copy inside a closure or another property, the next mutation copies the whole buffer. In hot loops, make sure the array you mutate isn’t shared.
Part 2: Dictionaries
Creating and reading
A dictionary maps unique keys to values. Keys must conform to Hashable:
var capitals = ["France": "Paris", "Japan": "Tokyo"]   // [String: String]
var stock: [String: Int] = [:]
A lookup returns an optional, because the key might not be there:
let capital = capitals["France"]        // String? -> "Paris"
let missing = capitals["Atlantis"]      // nil

if let tokyo = capitals["Japan"] {
    print("Capital of Japan: \(tokyo)")
}

let apples = stock["apples", default: 0]   // a fallback instead of an optional
Writing
capitals["Italy"] = "Rome"                          // insert
capitals["Japan"] = "Tōkyō"                         // update
capitals["France"] = nil                            // remove

let previous = capitals.updateValue("Kyoto", forKey: "Japan")   // returns "Tōkyō"
let removedCity = capitals.removeValue(forKey: "Italy")         // returns "Rome"
The default: subscript is also writable, which makes counting and grouping concise:
var frequencies: [String: Int] = [:]
for word in ["swift", "is", "fun", "swift"] {
    frequencies[word, default: 0] += 1
}
// ["swift": 2, "is": 1, "fun": 1]
Merging and transforming
var inventory = ["apples": 3, "pears": 1]
inventory.merge(["apples": 2, "plums": 5]) { current, new in current + new }
// apples: 5, pears: 1, plums: 5

let doubled = inventory.mapValues { $0 * 2 }                  // keys unchanged
let parsed = ["a": "1", "b": "x"].compactMapValues { Int($0) } // ["a": 1]
let plenty = inventory.filter { $0.value >= 5 }              // still a Dictionary
Building dictionaries from sequences
struct User {
    let id: Int
    let name: String
    let team: String
}

let users = [
    User(id: 1, name: "Sam", team: "iOS"),
    User(id: 2, name: "Lina", team: "Android"),
    User(id: 3, name: "Omar", team: "iOS"),
]

// Index by ID. Traps at runtime if two users share an ID.
let usersByID = Dictionary(uniqueKeysWithValues: users.map { ($0.id, $0) })

// Safe with duplicates: you decide which value wins.
let latestNameByTeam = Dictionary(users.map { ($0.team, $0.name) }, uniquingKeysWith: { _, newer in newer })

// Group into arrays.
let byTeam = Dictionary(grouping: users, by: { $0.team })
print(byTeam["iOS"]?.map { $0.name } ?? [])   // ["Sam", "Omar"]
Only use uniqueKeysWithValues when duplicate keys are impossible. With data from a server, duplicates happen, and the trap takes your app down. uniquingKeysWith: is the safe default.
Order is not guaranteed
Dictionaries are unordered. Don’t rely on the order you inserted things in, or the order you saw last time. Sort whenever order matters:
for (country, city) in capitals.sorted(by: { $0.key < $1.key }) {
    print("\(country): \(city)")
}
Under the hood: how Dictionary works
A hash table with open addressing
Swift’s native Dictionary is a hash table. To find a key, it computes the key’s hash value, maps it to a bucket in a contiguous array of buckets, and checks that bucket. If the bucket holds a different key (a collision), it probes the following buckets until it finds the key or an empty bucket. This technique is called open addressing with linear probing, and it’s very cache-friendly, because neighboring buckets sit next to each other in memory.
When the table gets too full, it allocates a bigger one and reinserts every element. Like array growth, this happens rarely enough that inserting is amortized O(1). Lookups are O(1) on average, but they rely on a good hash function: if many keys produced the same hash, every lookup would degrade into a linear scan.
reserveCapacity(_:) exists for dictionaries too, and avoids those rebuilds when you know the final size.
Randomized hashing
Swift seeds its hash function with a random value per process. The same program, run twice, produces different hash values, and therefore different dictionary orders:
let order = ["a": 1, "b": 2, "c": 3, "d": 4, "e": 5].map { $0.key }.joined()
print(order)                 // e.g. "edabc", then "acdbe" on the next launch
print("swift".hashValue)     // a different number on every launch
This protects apps against hash-flooding attacks, where an attacker sends keys chosen to collide and slows a server to a crawl. It also means you must never persist hashValue or rely on dictionary order in tests.
Writing a correct Hashable type
For your own key types, let the compiler synthesize Hashable whenever you can:
struct GridPoint: Hashable {
    var x: Int
    var y: Int
}

var visited: [GridPoint: Bool] = [GridPoint(x: 0, y: 0): true]
If you implement it by hand, follow one rule: values that are equal must have equal hashes. Hash exactly the properties that == compares:
struct Account: Hashable {
    let id: UUID
    var displayName: String          // changes over time, so not part of identity

    static func == (lhs: Account, rhs: Account) -> Bool {
        lhs.id == rhs.id
    }

    func hash(into hasher: inout Hasher) {
        hasher.combine(id)           // the same property that == uses
    }
}
And never mutate a key after it’s in a dictionary in a way that changes its hash. With value-type keys that’s impossible by design; with class keys, it silently corrupts lookups: the entry stays in the bucket of its old hash, where no lookup will ever look.
Performance cheat sheet
| Operation | Array | Dictionary |
|---|---|---|
| Read by index / key | O(1) | O(1) average |
| Append / insert new key | O(1) amortized | O(1) amortized |
| Insert or remove at the front | O(n) | — |
| Remove last | O(1) | — |
contains / search by value |
O(n) | O(1) by key, O(n) by value |
| Copy | O(1) (CoW), O(n) on first write | O(1) (CoW), O(n) on first write |
If you call contains on an array inside a loop, you’ve written an O(n²) algorithm. Convert the array to a Set or Dictionary once and look up in O(1).
Common pitfalls
Removing while iterating by index. This crashes as soon as the array shrinks:
var tasks = ["a", "b", "c", "d"]
// for i in 0..<tasks.count {
//     if tasks[i] == "b" { tasks.remove(at: i) }   // crash: index out of range later
// }
tasks.removeAll { $0 == "b" }   // safe, and O(n)
Mutating an array inside its own for-in loop. It doesn’t crash, because the loop iterates over a copy of the original, but the loop won’t see the new elements, which surprises people.
Assuming slice indices start at 0. Use startIndex or iterate directly.
Force-unwrapping dictionary lookups. dict[key]! is a crash waiting for one missing key. Use if let, guard let, or default:.
Sharing class instances in “copied” arrays. Copying an array of class instances copies the references, not the objects. Changing copy[0].name changes the object that original[0] points to as well.
Concurrent mutation. Arrays and dictionaries aren’t thread-safe. Two threads appending to the same array at the same time can corrupt it or crash. Confine each collection to one thread, or protect it with a serial DispatchQueue:
final class SafeLog {
    private var entries: [String] = []
    private let queue = DispatchQueue(label: "SafeLog")

    func add(_ entry: String) {
        queue.sync { entries.append(entry) }
    }

    var all: [String] {
        queue.sync { entries }
    }
}
Interview questions
Why is appending to an array O(1) if it sometimes copies everything? Because the capacity grows geometrically, roughly doubling. Copies get rarer as the array grows, so the total work for n appends is O(n), which averages out to O(1) per append (“amortized”).
What’s copy-on-write, and how would you implement it?
Copies share storage until one is mutated. Implement it with a private class holding the data, and check isKnownUniquelyReferenced(&storage) before every mutation, copying only when the storage is shared.
Why does a dictionary’s order change between launches? Swift seeds hashing randomly per process, to defend against hash-flooding attacks. Order depends on hash values, so it changes too.
What breaks if hash(into:) and == disagree?
Equal keys could land in different buckets, so lookups miss entries that are there, and duplicates can appear. Equal values must always produce equal hashes.
Summary
Arrayis ordered and indexed; out-of-range subscripts crash, so usefirst,last,indices, andfirstIndex(of:)when unsure.- Arrays grow geometrically (amortized O(1) appends), and
reserveCapacityavoids reallocations. - Slices share storage and keep the original indices; convert to
Arraybefore storing them. - Both types use copy-on-write: copies are free until the first mutation.
Dictionaryis a randomized-seed hash table with open addressing: O(1) average lookups, no stable order, andHashablekeys whose hash must agree with==.